Key Takeaways
- A review section is the largest unpaid quality department a toy brand will ever run — read it like an inspector, not a marketer.
- Durability, smell and surprise explain most of the star distribution in this category.
- "Destroyed in days" is a specification problem wearing a review's clothes: material, seams or size-to-breed mismatch, each with a different owner.
- Smell complaints start in the compound room, long before the parcel is sealed — control them in the order, not in reply templates.
- Surprise — an odd-angle squeal, an erratic bounce — is a positive driver that can be designed, prototyped and tested.
A review section is the largest unpaid quality department a pet toy brand will ever run: hundreds of inspectors, none on payroll, testing products in real homes with real dogs and no patience for marketing language. Most brands scroll this department's reports for sentiment. The useful move is to read them like an inspector — and once you do, three themes explain most of the star distribution in this category: durability, smell and surprise.
Two of those are failure modes and one is a delight mechanism. All three trace back to decisions made before production, which is what makes reviews actionable rather than merely painful.
The Three Themes Behind Most Star Ratings
Strip away breed anecdotes and the wording collapses into recurring patterns, each with a distinct production cause:
| Theme | Typical wording | Upstream cause | Who owns the fix |
|---|---|---|---|
| Durability | "Tore apart in two days," "fluff everywhere" | Material choice, seam configuration, or size-to-breed mismatch | Product spec, with the factory's sewing and compound teams |
| Smell | "Smells like chemicals," "reeked of tires" | Recycled content ratio, process oils, packaging off-gassing | Compound selection and the airing protocol before packing |
| Surprise | "He carries it everywhere," "lost interest in an hour" | Play-value design: squeaker placement, bounce geometry, texture mix | Design and range curation |
The table matters because the three themes travel through different channels. Durability complaints are spec conversations; smell complaints are procurement conversations; surprise feedback is a design conversation. Routing all of them to "customer service" guarantees none of them gets fixed.
One practical habit: tag every review with one of the three themes in the week it arrives. Tagging forces the wording into buckets while it is fresh, and a quarter of tagged data is enough to show which theme your range actually has a problem with — most brands discover it is not the theme they feared.
Reading One-Star Reviews Like an Inspector
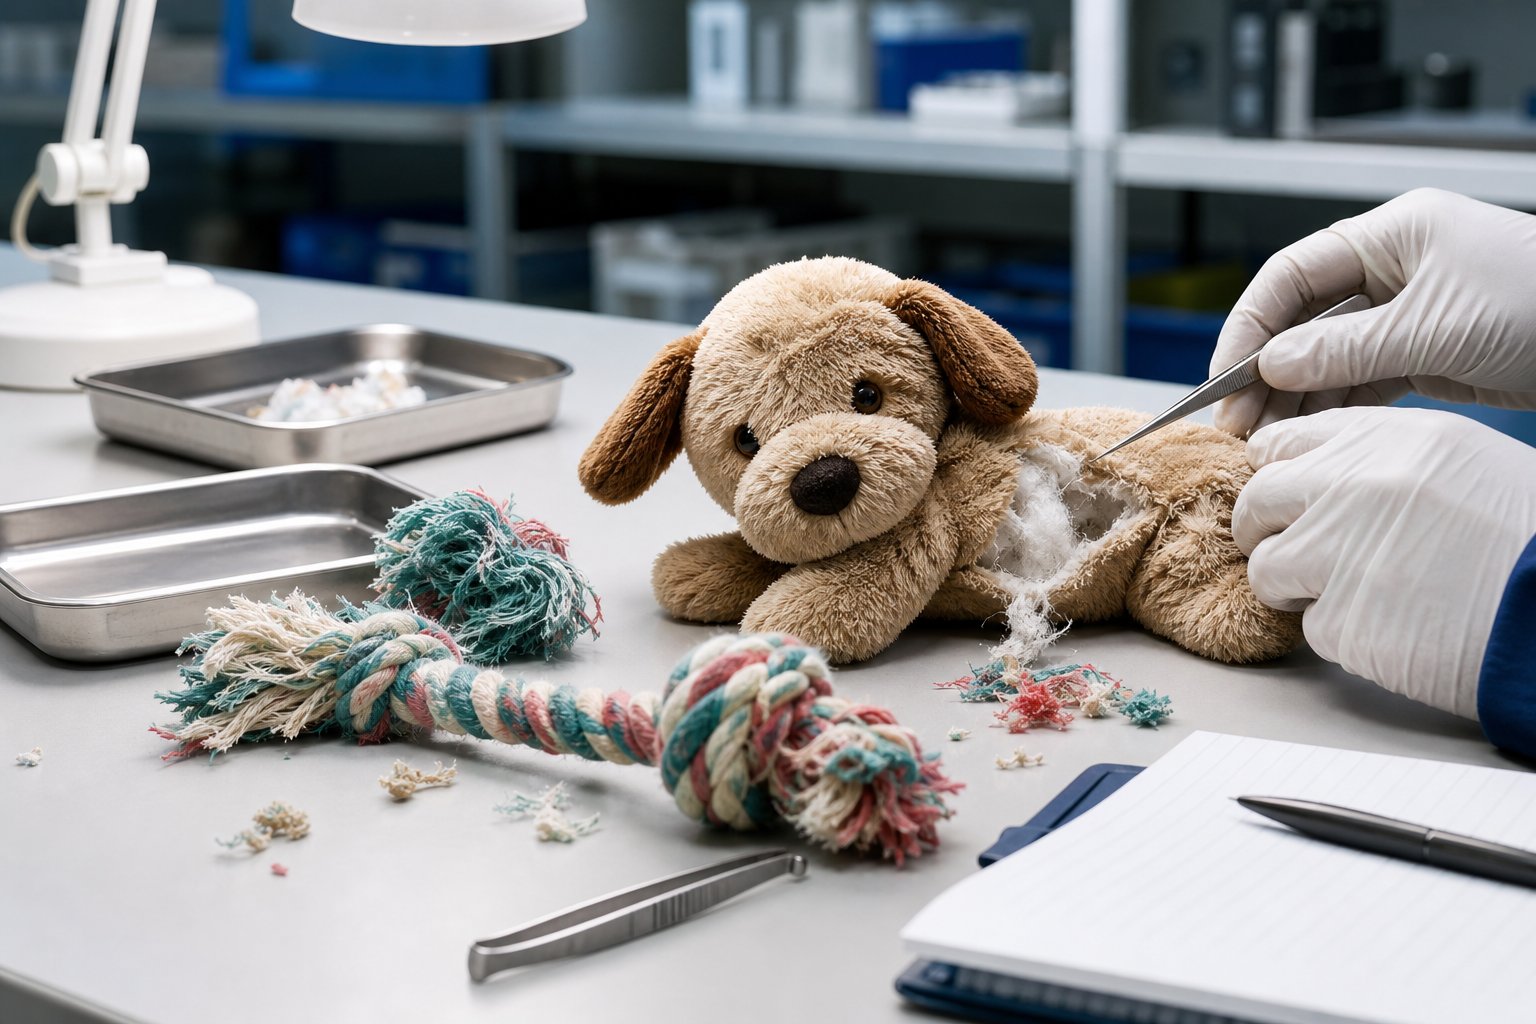
Start by splitting durability complaints into failure modes, because a toy can fail in at least five ways that look identical in a one-line review: a seam that opened (sewing), a fabric that shredded (fabric weight against tooth strength), rubber that chunked (compound tear quality), a squeaker that died in a week (weld or diaphragm), and a toy that was simply too small for the jaws it met (labeling). Each maps to a different department and a different fix.
Photo reviews are gold here. A clean seam split reads differently from a shredded fabric edge or a chunked rubber bite mark, and the difference tells you whether to adjust stitch density, upgrade fabric weight or change compound grade. Frequency does the rest: one SKU with a seam problem is a design issue, three SKUs with the same seam problem is a production-line issue, and the distinction decides whether you edit a product or a factory.
The Surprise Dividend
Not every review theme is a complaint waiting to be engineered away. Five-star wording in this category clusters around a single emotion: delight. "He squeals it at 3 a.m." and "she catches it mid-bounce" are reports of surprise — the toy did something the dog did not predict. Surprise is designable: squeakers that respond at odd angles, bounce geometry that changes direction, crinkle panels hidden where a nose would hunt, textures that alternate under a paw.
It is also testable before launch. Short play sessions with dogs of different jaw styles separate genuine surprise from novelty that fades in an afternoon, and factories can turn design variations around quickly — plush sample iterations run on a scale of days to a couple of weeks by common industry practice. The brands with magnetic review sections are not lucky; they treat play value as a tested feature with the same seriousness others reserve for tear strength.
Watch the language of delight too: carries it everywhere, brings it to bed, squeaks it at the door. Those phrases are reorder signals — the review section telling you which SKU has earned the next video and the next variant.
Wiring Reviews Back Into the Next Order
A review digest is only as useful as the clauses it feeds. The workable loop has three steps. First, translate themes into measurable order terms: durability complaints become batch durometer readings and seam specifications, smell complaints become a sensory check before packing with agreed remedies, squeaker deaths become pull tests on attachment strength. Our quality standards page lists the tests we run against exactly these themes, and the smell conversation is unpacked further in our piece on odor control in rubber and TPR production. Put odor into the AQL defect catalog as well, so a failing batch has a documented disposition instead of a hopeful one.
Second, share the digest with the supplier quarterly — a short table of themes, frequencies and affected SKUs is enough. Third, verify at reorder: compare production against the golden sample, and add any new failure mode to the inspection standard the same week it appears. Durability wording on the listing should evolve with the evidence too; our guide to chew-strength ratings shows how to keep durability claims honest as the data accumulates.
The Compliance Line in Review Operations
Because reviews carry so much weight, the temptation to nudge them is permanent — and the line is sharp. Offering refunds, gifts or discounts in exchange for a review violates marketplace policies even when the review is negative-to-positive neutral. Conditioning a replacement on a customer editing or removing a review is treated as suppression. Asking for honest feedback after delivery, on the other hand, is normal, expected practice everywhere. The sustainable posture is mechanical: ask neutrally, read everything, never trade, and let the fixes show in the next hundred reviews instead of the next email.
Frequently Asked Questions
How many reviews do I need before patterns mean anything?
Is it acceptable to ask customers for reviews?
Which should be fixed first, durability or smell?
Can a supplier really reduce review complaints?
Reviews pointing at durability or smell?
Send the complaint themes — we map them to materials, tests and the order clauses that prevent them, with FOB ranges for the corrected spec.